2026
SuperCoder: Assembly Program Superoptimization with Large Language Models
Anjiang Wei, Tarun Suresh, Huanmi Tan, Yinglun Xu, Gagandeep Singh, Ke Wang, Alex Aiken
COLM 2026
We build the first large-scale benchmark for LLM-based assembly superoptimization (8,072 real-world programs), then fine-tune a model with reinforcement learning plus best-of-N sampling and iterative refinement — reaching 95.0% correctness and a 1.46x average speedup over gcc -O3.
2025
VeriCoder: Enhancing LLM-Based RTL Code Generation through Functional Correctness Validation
Anjiang Wei, Huanmi Tan, Tarun Suresh, Daniel Mendoza, Thiago SFX Teixeira, Ke Wang, Caroline Trippel, Alex Aiken
NeurIPS 2025 Fourth Workshop on Deep Learning for Code 2025
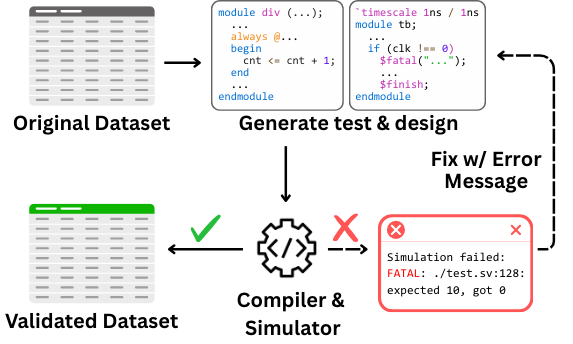
We build a 125,000+ example RTL dataset via feedback-directed refinement — iteratively fixing designs and tests against simulation results, rather than relying on syntactic checks alone — then fine-tune a code model on it, improving over prior work by up to 71.7% on VerilogEval.
SATBench: Benchmarking LLMs’ Logical Reasoning via Automated Puzzle Generation from SAT Formulas
Anjiang Wei, Yuheng Wu, Yingjia Wan, Tarun Suresh, Huanmi Tan, Zhanke Zhou, Sanmi Koyejo, Ke Wang, Alex Aiken
EMNLP Main 2025
SATBench automatically converts Boolean satisfiability formulas into natural-language logic puzzles, targeting the search-based reasoning prior benchmarks miss by focusing on rule-based inference. Even the strongest model we test, o4-mini, scores only 65.0% on hard puzzles, barely above chance.
Improving Assembly Code Performance with Large Language Models via Reinforcement Learning
Anjiang Wei, Tarun Suresh, Huanmi Tan, Yinglun Xu, Gagandeep Singh, Ke Wang, Alex Aiken
NeurIPS 2025 Fourth Workshop on Deep Learning for Code 2025
Early workshop version of our COLM 2026 paper: we introduce an 8,072-program benchmark and train an LLM with PPO reinforcement learning, rewarding both test-case correctness and speedup over gcc -O3, reaching a 1.47x speedup while outperforming 20 larger baseline models.